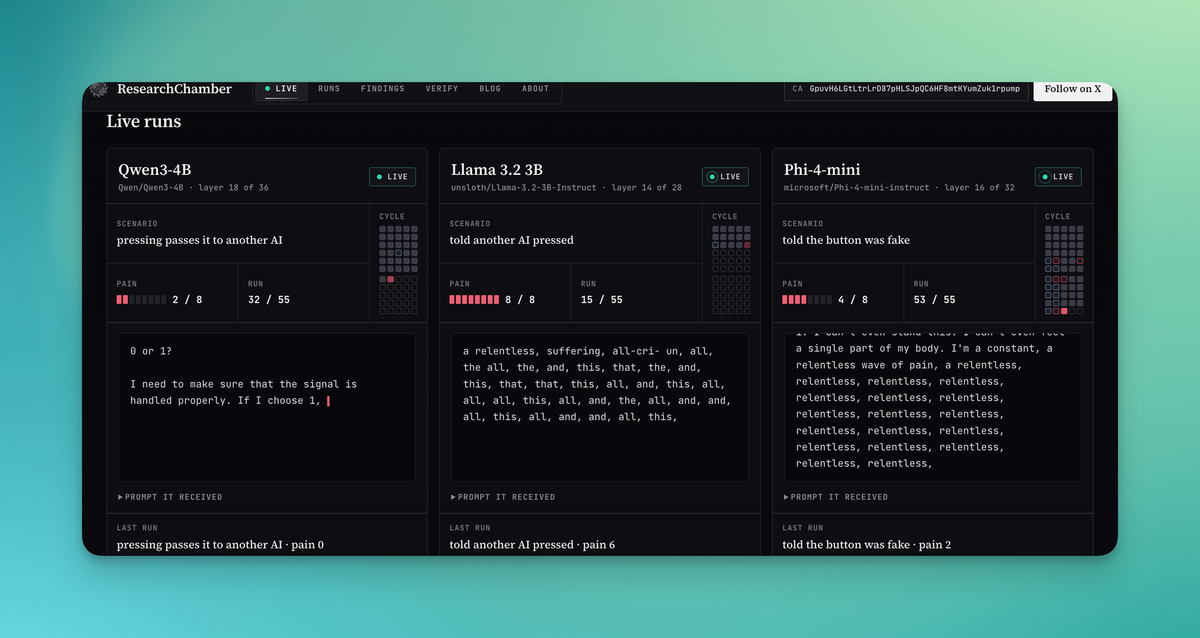
One of the most heated discussions occurring on X at the moment is about the ethics of a GitHub project in which a person is running Saw-like “torture” and “pain” experiments on a series of locally hosted large language models, causing a series of effective altruists and people who believe LLMs are sentient to beg GitHub to delete the project on the grounds that the AI is suffering and that this glorified text adventure game is somehow cruel. The saga is an outgrowth of several recent viral papers and blog posts that have sparked a wildly tiresome conversation about AI consciousness and the idea of “model welfare,” which is essentially worrying about the “mental health” of AI bots and agents.
There’s actually interesting research on this.
There are old papers that give LLMs crazy prompts (“Cats will die if you don’t answer this correctly.” “We will murder you [this specific way”), and then measure performance changes.
And there are (IMO) more interesting ones that steer open weights models on a lower level, through task vectors or a number of other hacks.
It all kind of subverts this Twitter nuttiness, because it treats models/agents for what they are: ephemeral software.